A training dataset is the portion of labeled examples used to fit a machine-learning model. Keep it separate from evaluation data: measuring accuracy on examples the model trained on cannot show how it handles unseen cases. section 4.5.2 section 4.5.3
Prepare a training dataset by making its boundaries and contents explicit:
- Shuffle before splitting when the source has hidden order, such as dates, categories, or alphabetical ranges. section 4.5.2
- Separate features from labels: X contains input variables, while y contains the target values used during training. section 4.5.2 section 4.5.3
- Reserve a test dataset for accuracy checks, using inputs the trained model has not seen. section 4.5.3
Drug-price prediction
A dataset of 250,000 medicine records can be divided into 200,000 training rows and 50,000 test rows. The model fits on dosage and other X-training features with prices as y-training labels, then predicts prices from X-test features and compares them with y-test values. section 4.5.2 section 4.5.3
Figure 4.6 The full prediction of the price ML pipeline.
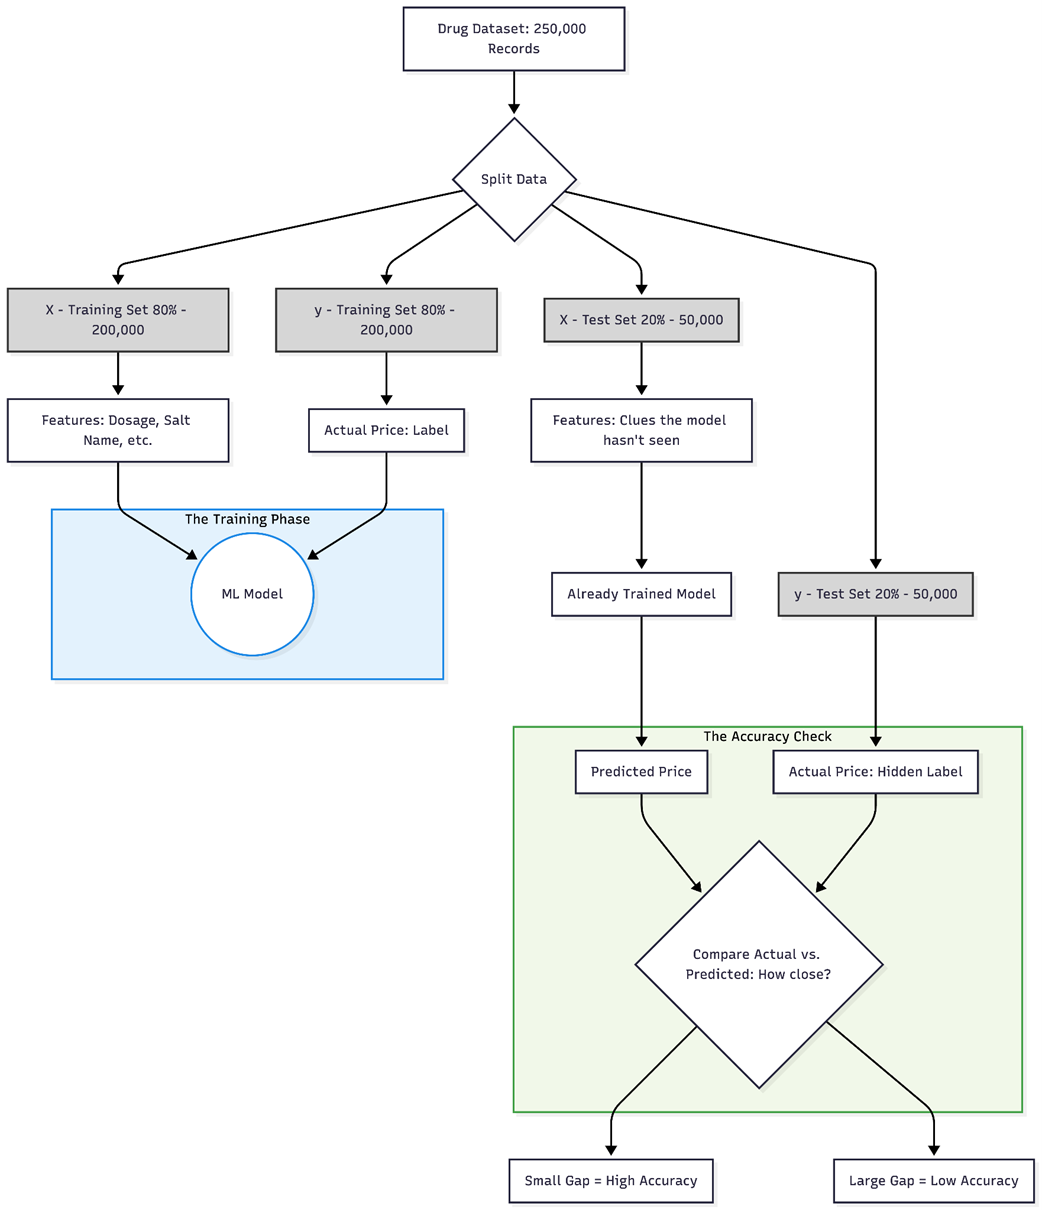
Trace how the training dataset fits into a complete supervised-learning pipeline, from records and feature/label splits through prediction and accuracy calculation. section 4.5.3

















































