A training dataset is the portion of available data used to fit a model. Imagine studying 80 exam questions carefully, then answering 20 different questions without looking at the answers: the 80 questions are like training data, while the 20 are held out for testing. section 4.2
A reliable model-building workflow separates each job:
- Use the training dataset to fit every candidate model. section 4.15
- Use a validation set to choose the model or its hyperparameters. section 4.5
- Use the testing dataset only at the end to estimate performance on unseen data. section 4.4
Splitting a polynomial-regression dataset
A dataset shaped like a downward-opening parabola can be expanded into polynomial features and divided into training and testing portions. In scikit-learn, train_test_split creates the split; the model then fits only X_train and Y_train. Comparing training and testing errors reveals whether a simple model underfits or a complex model overfits. section 4.14 section 4.2
Figure 4.8 The dataset. Notice that its shape is a parabola that opens downward, so using linear regression won’t work well. We’ll use polynomial regression to fit this dataset, and we’ll use regularization to tune our model.
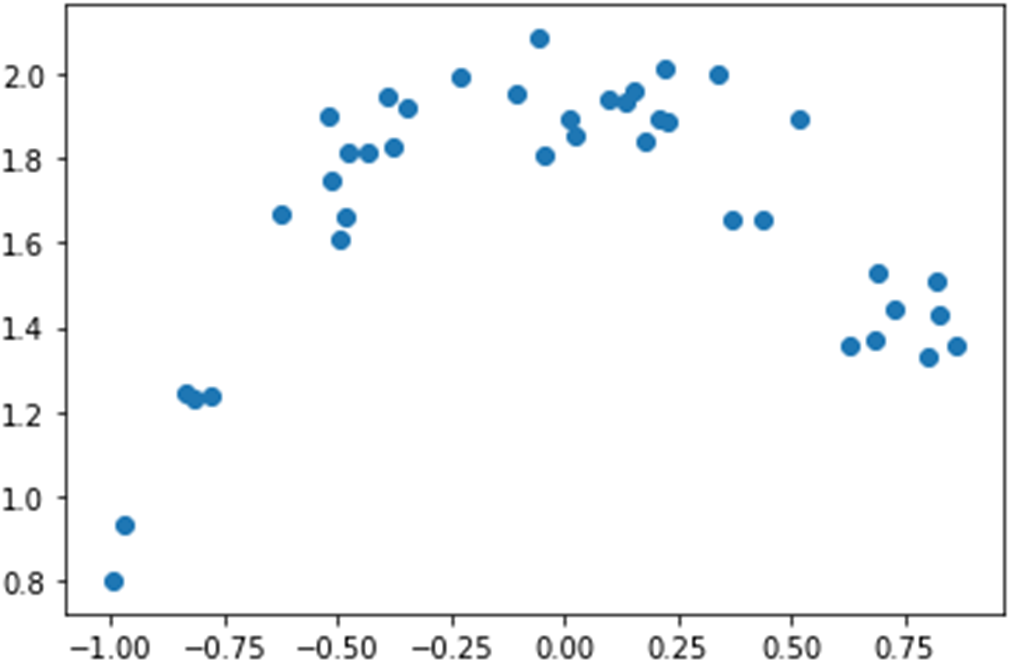
Use the dataset figure to see why the training examples need a model whose shape captures the underlying pattern rather than merely memorizing points. section 4.14

















































