Fine-tuning refines a model’s training to better match a particular use case or domain. It can make a model more relevant for a domain-specific agent. section 2.0 section 2.4
From general training to chat
ChatGPT is trained on public-internet content, then fine-tuned using several strategies, including reinforcement learning with human feedback (RLHF). section 2.0
Figure 2.2 The main elements that describe an LLM
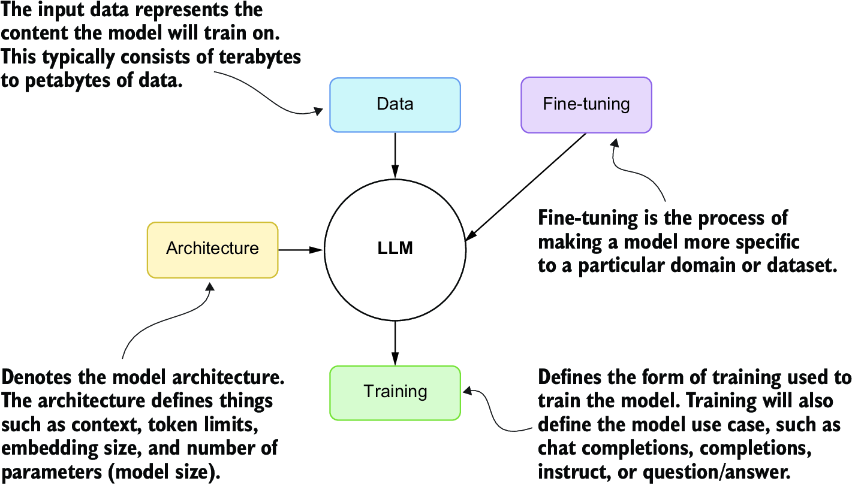
See how fine-tuning fits alongside data and architecture as an element of an LLM. section 2.0



















































