Fine-tuning adapts a pretrained GPT model through further supervised training on labeled task data. For conversational behavior, the data pairs questions as inputs with manually labeled answers as outputs, teaching the model to answer prompts rather than simply continue text. section 5.2.1
In the illustrated ChatGPT training sequence:
- Pretraining learns from a large text corpus without output labels and consumes the most compute and training time. section 5.2.1
- Supervised fine-tuning uses labeled question-and-answer pairs to shape responses to prompts. section 5.2.1
- Reinforcement learning further tunes the supervised model using a reward model trained from human rankings or scores. section 5.2.1
Figure 5.12 Demonstration of Supervised Fine-Tuning of a ChatGPT model.
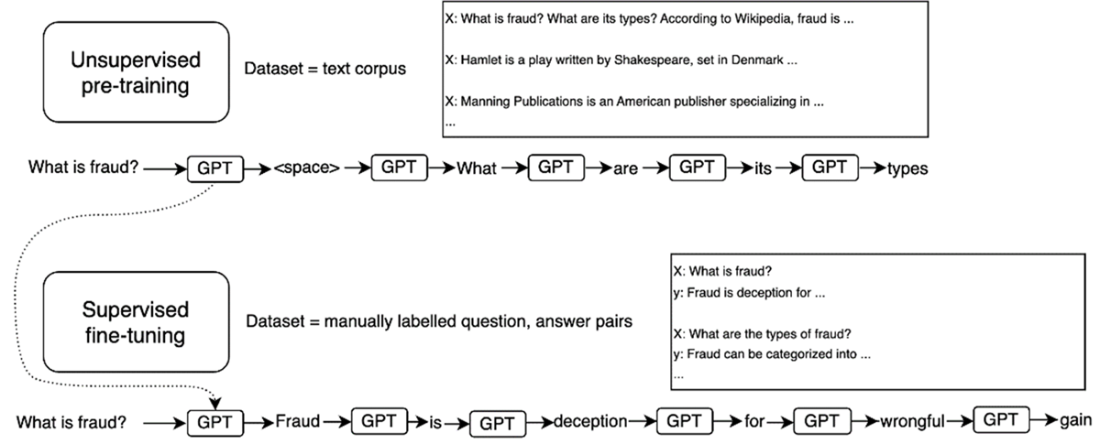
Compare unlabeled pretraining data with the paired inputs and outputs used for supervised fine-tuning. section 5.2.1



















































