Monitoring tracks known indicators of system health, such as CPU usage, error rates, response times, and availability. It works when a team can define what “good” and “bad” look like, then use dashboards and alerts to detect a change. Observability is broader: it helps investigate system behavior, including failures the team did not anticipate. Monitoring is one part of that wider capability. section 1.3.3 section 10.3.1
A useful alert needs a path to diagnosis. Metrics can reveal that a server is overloaded or HTTP errors are rising; detailed logs can show the events that led there; traces can connect a request across processes. Collect the necessary signals from applications and infrastructure rather than relying on default metrics alone. section 5.1.1
Monitor the platform from outside it
Suppose several Kubernetes clusters support production services. Dashboards hosted only inside each cluster may disappear when a cluster or its ingress fails—the moment they are most needed. Keep basic collection near the workloads, but use dedicated infrastructure to aggregate observability data. An external service can check both the clusters and the observability platform, then alert the team if either fails. section 5.3.3
Build monitoring incrementally around decisions teams need to make:
- Define service objectives from user needs and business priorities; select indicators for critical services such as payment processing. section 10.4.2
- Configure dashboards and alerts for known health indicators, then connect alerts to logs and traces for investigation. section 10.3.1 section 5.1.1
- Check that data collection and alerting still work when the platform itself is unavailable. Use monitoring data to compare a new platform capability’s actual value with its initial estimate. section 5.3.3 section 2.3.1
Figure 5.10 Observing your engineering platform should be done external to the platform itself. Otherwise, you risk not being alerted properly about a total outage because the observability system would also be down. Similarly, your observability platform is an equally critical system component and should also be observed externally.
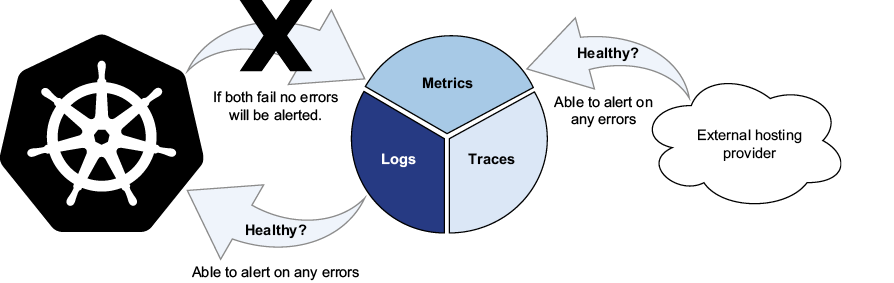
The diagram shows why an engineering platform and its observability system need checks from outside the platform: an internal outage can otherwise silence its own alerting. section 5.3.3







































