A deployed Kafka system can run without errors and still fall behind or exhaust its resources. Monitoring collects metrics that show whether applications and clusters remain healthy and efficient, including CPU, memory, disk, network, throughput, and consumer lag. Alerts should reach operations teams when failures, resource exhaustion, or unexpected behavior require action; timely diagnosis helps protect service level objectives. section 11.2 section 11.2.3
Consumer lag is a particularly important signal: it indicates how far a consumer group is behind the messages produced to a partition. It can be read from a Kafka JMX metric or estimated from committed and latest produced offsets. The offset calculation is approximate because offsets can be missing. Rising lag can inform a decision to scale consumers, though the number of partitions limits how many consumer instances can process a group’s workload in parallel. section 4.3.1
Different signals answer different operational questions:
- Infrastructure and JVM metrics reveal resource pressure; cloud providers may collect many of these automatically. section 11.2 section 11.2.3
- Kafka-specific and business-level metrics reveal behavior that generic application health checks can miss. Developers and operations teams must agree who instruments and maintains them. section 11.2.3
- Logs and traces help follow data through chained Kafka Streams processors when metrics alone cannot locate an error or bottleneck. Distributed tracing tools include OpenTelemetry, Jaeger, and Zipkin. section 8.5.6
Centralized logs across services
In a Customer 360 operational data store, several services generate data while another aggregates it. Logs kept only on local filesystems make cross-service trouble hard to trace. A shared collection flow sends application log events through Kafka to Elasticsearch or OpenSearch for indexing, then exposes them through Kibana or OpenSearch Dashboards. Standardizing how applications format and emit events makes activity easier to track across languages and frameworks. section 5.1.3
Figure 5.6 Conceptual flow for log data collection: log data is sent from the application to Kafka for processing, then indexed in Elasticsearch, and finally visualized in Kibana.
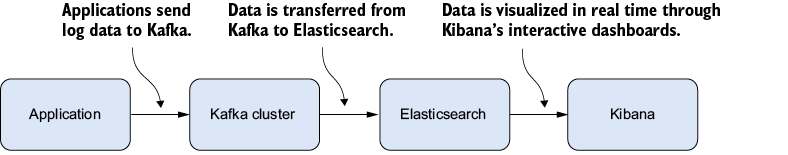
The diagram separates log transport through Kafka from indexing in Elasticsearch and visualization in Kibana. section 5.1.3
Monitoring is an ongoing responsibility, not a dashboard installed once. Managed Kafka can shift infrastructure monitoring to a provider, while self-managed clusters require continuous attention to cluster health. Governance may also require logging and data-profiling guidelines, audits, and reviews. Kafka’s commit log is different from application logging: it stores ordered messages for consumers, rather than serving as a substitute for operational logs and metrics. section 11.0 section 7.2.3 section 1.4.3







































