A probability distribution assigns each possible outcome a value between 0 and 1, with all values summing to 1. Softmax turns model scores into such a distribution. section 2.2.3 section 4.2.4
In knowledge distillation, a teacher’s full distribution gives a student more than a hard label: probabilities for alternative classes reveal their relative similarity and the teacher’s confidence. section 8.2.1 section 8.9
Temperature changes the signal
For cat, dog, fox, and bird logits [5, 3, 1, −1], softmax at T=1 gives [0.865, 0.117, 0.016, 0.002]. At T=3 it gives [0.523, 0.268, 0.138, 0.071], making relationships among alternatives more visible; at T=10 it approaches a uniform distribution and weakens the signal. section 8.3.2
Figure 8.6 Learning from a recipe book (hard labels) gives you the correct answer but no context, while learning from a master chef (soft labels) reveals the relationships between alternatives. The dark knowledge that enables deeper understanding.
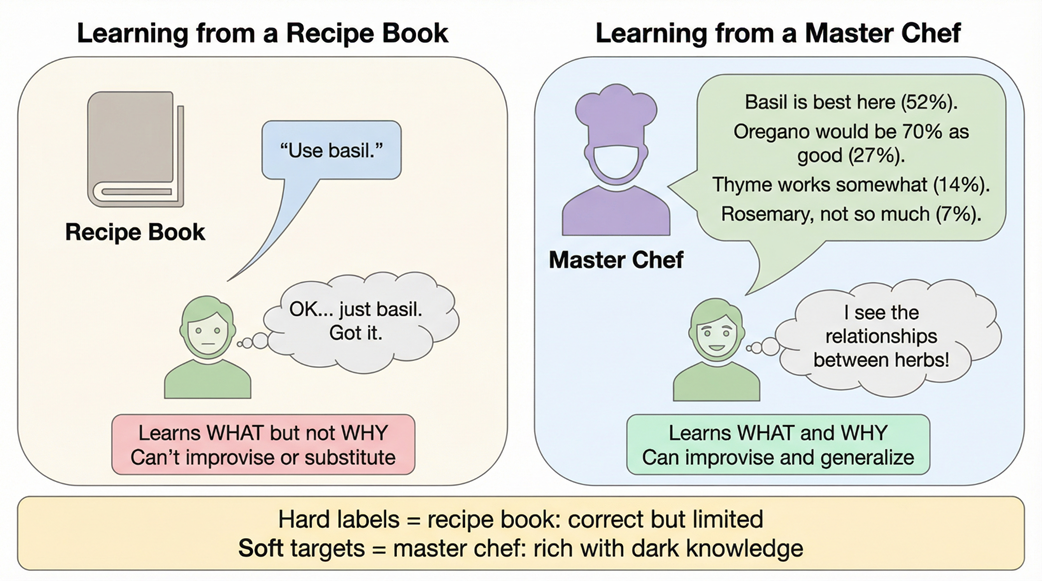
The master-chef analogy contrasts a hard label’s single answer with a distribution’s richer guidance about alternatives. section 8.2.2