A large language model powers the answer-generation stage of enterprise RAG. It can produce fluent, plausible responses, but may hallucinate facts, making retrieval accuracy, current data, consistency, and graceful uncertainty essential. section 1.2
Production use treats the model as one component in a broader workflow:
- Ground responses in appropriate, up-to-date databases rather than trusting generation alone. section 1.2
- Set expectations by communicating capabilities, limitations, and a graceful no-answer response. section 1.2
- Monitor latency, cost, consistency, and legal or reputational consequences as usage scales. section 1.2
Failure-sensitive customer questions
A customer asking about product availability or features may receive a confident but false answer; an airline chatbot promise demonstrates the potential legal consequences. section 1.2
Figure 1.6 A naive RAG pipeline with limited steps for retrieving answers. Suitable for simple queries but insufficient for handling complex or large-scale enterprise needs.
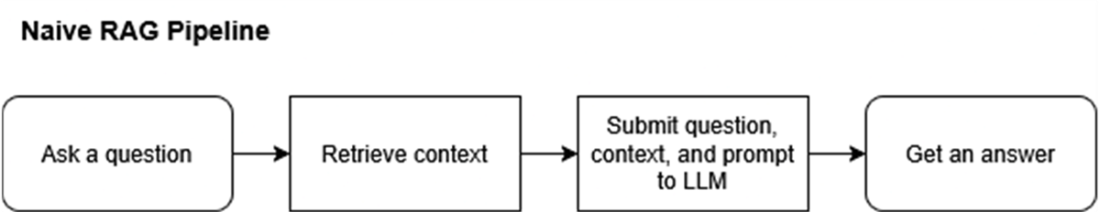
Use the naive RAG pipeline to locate the model within a retrieval-and-answer workflow and see why limited pipelines do not suit complex enterprise queries. section 1.2
























































































